<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://boosterkrd.github.io/feed/planet.xml" rel="self" type="application/atom+xml" /><link href="https://boosterkrd.github.io/" rel="alternate" type="text/html" hreflang="en" /><updated>2026-09-15T08:58:06+02:00</updated><id>https://boosterkrd.github.io/feed/planet.xml</id><title type="html">Booster’s Blog | Planet</title><subtitle>PostgreSQL engineering notes</subtitle><author><name>Marat Bogatyrev</name></author><entry><title type="html">Huge Pages in PostgreSQL</title><link href="https://boosterkrd.github.io/2026/09/07/postgresql-huge-pages.html" rel="alternate" type="text/html" title="Huge Pages in PostgreSQL" /><published>2026-09-07T00:00:00+02:00</published><updated>2026-09-07T00:00:00+02:00</updated><id>https://boosterkrd.github.io/2026/09/07/postgresql-huge-pages</id><content type="html" xml:base="https://boosterkrd.github.io/2026/09/07/postgresql-huge-pages.html"><![CDATA[<p>Your server keeps a <strong>page table</strong> — a structure in RAM that only describes where other memory is located. Each process has its own, with one 8-byte entry for every 4 KB page it has actually used. In PostgreSQL, every connection has its own backend, and each backend is a separate OS process — so each one holds a private description of the same <code class="language-plaintext highlighter-rouge">shared_buffers</code>. The more memory you give the database and the more connections you run, the more RAM is used just to describe memory you already own. On a typical production server with 32 GB of <code class="language-plaintext highlighter-rouge">shared_buffers</code> and 600 backends, this can easily reach 10 - 20 GB: RAM wasted on describing RAM.</p>

<!--MORE-->

<hr />

<h2 id="table-of-contents">Table of Contents</h2>

<ol>
  <li><a href="#1-the-problem-in-numbers">The problem, in numbers</a></li>
  <li><a href="#2-measure-your-own-server">Measure your own server</a></li>
  <li><a href="#3-how-it-works-under-the-hood">How it works under the hood</a></li>
  <li><a href="#4-postgresql-configuration">PostgreSQL configuration</a></li>
  <li><a href="#5-aside-a-pooler-may-be-enough">Aside: a pooler may be enough</a></li>
  <li><a href="#6-conclusion">Conclusion</a></li>
  <li><a href="#notes">Notes</a></li>
</ol>

<hr />

<h2 id="1-the-problem-in-numbers">1. The problem, in numbers</h2>

<p>The calculation is simple. Linux uses <strong>4 KB pages</strong> by default, and the kernel needs one <strong>8-byte entry</strong> to describe every page a process has touched:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>shared_buffers / 4 KB * 8 bytes = page table, per backend
</code></pre></div></div>

<p>With 32 GB of <code class="language-plaintext highlighter-rouge">shared_buffers</code>, that comes to about 8.4 million entries, or <strong>64 MB per backend</strong>. Nothing is shared — page tables are per-process, so the total can grow linearly with your connection count.<sup id="fnref:scaling" role="doc-noteref"><a href="#fn:scaling" class="footnote" rel="footnote">1</a></sup></p>

<p>This gives the upper limit — the cost if every backend has read all of <code class="language-plaintext highlighter-rouge">shared_buffers</code>:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: right">Backends</th>
      <th style="text-align: right">32 GB <code class="language-plaintext highlighter-rouge">shared_buffers</code></th>
      <th style="text-align: right">64 GB <code class="language-plaintext highlighter-rouge">shared_buffers</code></th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: right">10</td>
      <td style="text-align: right">0.62 GB</td>
      <td style="text-align: right">1.25 GB</td>
    </tr>
    <tr>
      <td style="text-align: right">100</td>
      <td style="text-align: right">6.25 GB</td>
      <td style="text-align: right">12.50 GB</td>
    </tr>
    <tr>
      <td style="text-align: right">300</td>
      <td style="text-align: right">18.75 GB</td>
      <td style="text-align: right">37.50 GB</td>
    </tr>
    <tr>
      <td style="text-align: right">600</td>
      <td style="text-align: right">37.50 GB</td>
      <td style="text-align: right">75.00 GB</td>
    </tr>
  </tbody>
</table>

<p>With 2 MB huge pages, the same 32 GB needs only 16,384 entries. That is roughly <strong>128 KB per backend</strong>, or 512x less.</p>

<blockquote>
  <p>ℹ️ <strong>A real case from production</strong>. With <code class="language-plaintext highlighter-rouge">shared_buffers = 32GB</code> and <strong>600 postgres processes</strong>, total page-table memory reached ~18 GB, or about 31 MB per process. This is half the upper limit because no backend had touched all of <code class="language-plaintext highlighter-rouge">shared_buffers</code>. With 2 MB pages, the same setup needed only <strong>75 MB total</strong>.</p>

  <p>CPU usage also dropped by roughly <strong>4 - 10%</strong>. Note what this number does not include. The freed memory was not used by anything. There was <em>no</em> OS page cache either, because that server stored its data on ZFS and caching happened in the ARC. It simply remained unused. <strong>Several gigabytes of RAM came back</strong>, and using them for a larger <code class="language-plaintext highlighter-rouge">shared_buffers</code> or more room for the ZFS ARC should increase the gain even further. The 4 - 10% is what you get before that.</p>
</blockquote>

<hr />

<h2 id="2-measure-your-own-server">2. Measure your own server</h2>

<p>Before you change anything, find out what it is actually costing you:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># 1. Page-table memory across the whole system</span>
<span class="nb">grep</span> <span class="s1">'^PageTables'</span> /proc/meminfo
</code></pre></div></div>

<div style="margin:-12px 0 22px;border-left:3px solid #b5e853;border-radius:0 8px 8px 0;overflow:hidden;background:#0d0d0d">
  <div style="font-family:Menlo,Consolas,monospace;font-size:10.5px;letter-spacing:.14em;text-transform:uppercase;color:#b5e853;padding:6px 14px;background:rgba(181,232,83,.09)">output</div>
  <pre style="margin:0;padding:12px 14px;background:transparent;border:0;border-radius:0;color:#d5dae2;font-size:13px;line-height:1.6;overflow-x:auto">PageTables:     19215332 kB</pre>
</div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># 2. Just PostgreSQL — total, and the average per process</span>
<span class="nb">awk</span> <span class="s1">'/VmPTE/ {t += $2; n++} END {if (n) printf "processes: %d\ntotal:     %.1f MB\nper proc:  %.1f MB\n", n, t/1024, t/n/1024}'</span> <span class="se">\</span>
    <span class="si">$(</span>pgrep <span class="nt">-x</span> postgres | <span class="nb">sed</span> <span class="s1">'s|.*|/proc/&amp;/status|'</span><span class="si">)</span>
</code></pre></div></div>

<div style="margin:-12px 0 22px;border-left:3px solid #b5e853;border-radius:0 8px 8px 0;overflow:hidden;background:#0d0d0d">
  <div style="font-family:Menlo,Consolas,monospace;font-size:10.5px;letter-spacing:.14em;text-transform:uppercase;color:#b5e853;padding:6px 14px;background:rgba(181,232,83,.09)">output</div>
  <pre style="margin:0;padding:12px 14px;background:transparent;border:0;border-radius:0;color:#d5dae2;font-size:13px;line-height:1.6;overflow-x:auto">processes: 602
total:     18662.0 MB
per proc:  31.0 MB</pre>
</div>

<p>This is a real server: <strong>18.2 GB of RAM used for page tables</strong> across 602 postgres processes, or 31 MB per process.</p>

<p><code class="language-plaintext highlighter-rouge">PageTables</code> in <code class="language-plaintext highlighter-rouge">/proc/meminfo</code> shows the system-wide figure, while <code class="language-plaintext highlighter-rouge">VmPTE</code> in <code class="language-plaintext highlighter-rouge">/proc/&lt;pid&gt;/status</code> shows it per process. On a database host, the two should be almost the same, and here they are: 18.3 GB system-wide versus 18.2 GB from PostgreSQL alone. That leaves about 100 MB for everything else on the server. If your numbers differ by much more than that, something other than PostgreSQL is using the memory, and you should find it first.</p>

<p>Then decide:</p>

<ul>
  <li><strong>A few hundred MB</strong>: huge pages are not your problem. Spend your effort elsewhere.</li>
  <li><strong>Several GB</strong>: you are paying a permanent memory tax to describe memory you already own, so a migration is worth the work. That RAM returns to the page cache and the rest of the system, which helps regardless of your workload. An I/O-bound server may be I/O-bound precisely because those gigabytes went into page tables instead of caching data.</li>
</ul>

<hr />

<h2 id="3-how-it-works-under-the-hood">3. How it works under the hood</h2>

<p>The mechanics of virtual addressing, the TLB, why a fault can happen when memory is already resident, and what a 2 MB page changes are covered in a separate interactive explainer:</p>

<p><strong><a href="/assets/posts/howtoworks_hugepages.html">→ Why PostgreSQL spends gigabytes on page tables</a></strong></p>

<p>It walks through the address translation path, the page table problem for each process, and the first-touch fault step by step. It also includes an explorer where you can enter your own <code class="language-plaintext highlighter-rouge">shared_buffers</code> value and backend count.</p>

<p>The short version, if you only want the conclusions:</p>

<ul>
  <li>Every memory access needs a virtual-to-physical translation. The CPU caches recent translations in the TLB, with roughly 2,000 entries. Every miss requires a four-level walk through the page table in RAM. The amount of memory those entries cover changes:
    <ul>
      <li><strong>With 4 KB pages</strong>: 2000 * 4 KB = <strong>8 MB</strong>. A 32 GB <code class="language-plaintext highlighter-rouge">shared_buffers</code> pool exceeds that constantly, so misses are the normal case.</li>
      <li><strong>With 2 MB pages</strong>: 2000 * 2 MB = <strong>4 GB</strong>. This still does not cover the full pool, and misses do not disappear, but they happen much less often than with 4 KB pages.</li>
    </ul>
  </li>
  <li><strong>Every connection gets its own backend, and every backend is a separate OS process</strong>, not a thread. Each backend carries a private page table. Backend B faults on a page that backend A has already touched, because B’s own table has no entry for it. In practice, warm-up is not shared.</li>
  <li>The faults are <strong>minor</strong>. There is no disk I/O, only a brief switch into the kernel to fill in the missing entry. That is why the cost is so easy to miss: there is no I/O wait to point at and no slow query to blame.</li>
</ul>

<p>This is also where the <strong>4 - 10%</strong> CPU from the case above came from: address translation alone. The TLB started covering a useful share of the working set instead of missing constantly.</p>

<h3 id="the-worst-case-an-empty-shared_buffers">The worst case: an empty <code class="language-plaintext highlighter-rouge">shared_buffers</code></h3>

<p>The effect is strongest while <code class="language-plaintext highlighter-rouge">shared_buffers</code> is still <strong>empty and being filled</strong>, because every access is a first touch. A <a href="https://read.thecoder.cafe/p/linux-broke-postgresql">Linux 7.0 change</a> made this clear in 2026: on a server with a very large <code class="language-plaintext highlighter-rouge">shared_buffers</code> and huge pages disabled, first-touch faults on the empty pool were enough to make PostgreSQL about two times slower. Huge pages cut the faults by 512x, and the regression disappeared.</p>

<hr />

<h2 id="4-postgresql-configuration">4. PostgreSQL configuration</h2>

<h3 id="huge_pages"><code class="language-plaintext highlighter-rouge">huge_pages</code></h3>

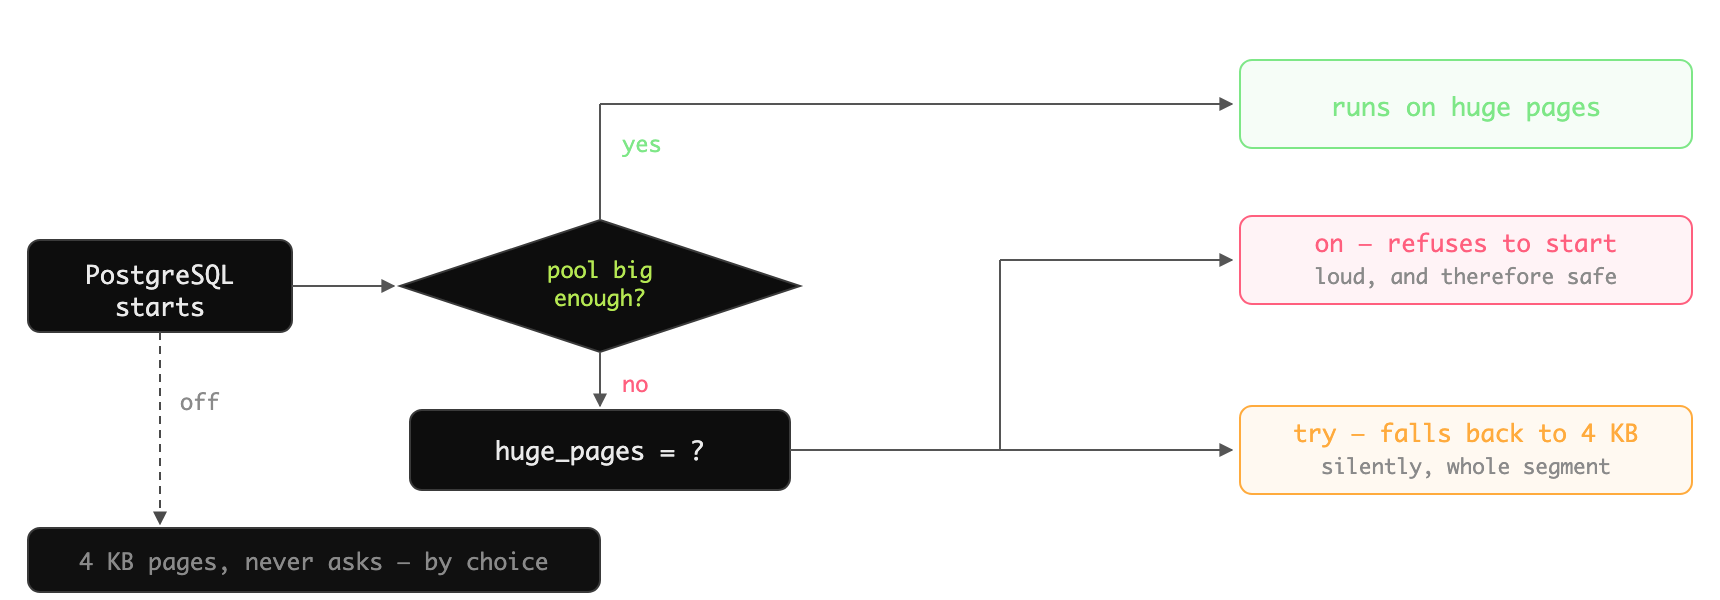
<p>The <a href="https://www.postgresql.org/docs/current/runtime-config-resource.html"><code class="language-plaintext highlighter-rouge">huge_pages</code> setting</a> takes three values:</p>

<table>
  <thead>
    <tr>
      <th>Value</th>
      <th>Behaviour</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">try</code></td>
      <td>Use huge pages if possible, silently fall back to 4 KB otherwise (default)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">on</code></td>
      <td>Require huge pages; <strong>refuse to start</strong> if unavailable</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">off</code></td>
      <td>Never use huge pages</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/hugepages-outcomes.png" alt="What happens at startup, depending on the reservation and the setting" /></p>

<p><code class="language-plaintext highlighter-rouge">on</code> fails loudly at startup if the required reservation is missing. <code class="language-plaintext highlighter-rouge">try</code> always starts, but it can silently fall back to 4 KB pages. If you use <code class="language-plaintext highlighter-rouge">try</code>, monitor separately that huge pages are actually in use.<sup id="fnref:try" role="doc-noteref"><a href="#fn:try" class="footnote" rel="footnote">2</a></sup></p>

<p>Since PostgreSQL 17, that check takes one line. <a href="https://pgpedia.info/h/huge_pages_status.html"><code class="language-plaintext highlighter-rouge">huge_pages_status</code></a> reports what the server actually got, not what it asked for:</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SHOW</span> <span class="n">huge_pages_status</span><span class="p">;</span>   <span class="c1">-- on | off | unknown</span>
</code></pre></div></div>

<p>Alert on any value other than <code class="language-plaintext highlighter-rouge">on</code>.<sup id="fnref:status" role="doc-noteref"><a href="#fn:status" class="footnote" rel="footnote">3</a></sup> On older versions, <code class="language-plaintext highlighter-rouge">/proc/meminfo</code> gives you most of the answer from the OS side. It shows whether the pool is in use, but not which process is using it:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">grep</span> <span class="nt">-E</span> <span class="s1">'HugePages_Total|HugePages_Free|HugePages_Rsvd|Hugetlb'</span> /proc/meminfo
</code></pre></div></div>

<div style="margin:-12px 0 22px;border-left:3px solid #b5e853;border-radius:0 8px 8px 0;overflow:hidden;background:#0d0d0d">
  <div style="font-family:Menlo,Consolas,monospace;font-size:10.5px;letter-spacing:.14em;text-transform:uppercase;color:#b5e853;padding:6px 14px;background:rgba(181,232,83,.09)">output</div>
  <pre style="margin:0;padding:12px 14px;background:transparent;border:0;border-radius:0;color:#d5dae2;font-size:13px;line-height:1.6;overflow-x:auto">HugePages_Total:   17000        <span style="color:#8b949e"># pool reserved: 17000 * 2 MB = 33.2 GB</span>
HugePages_Free:      232        <span style="color:#b5e853"># 99% taken → PostgreSQL got them ✓</span>
HugePages_Rsvd:       40        <span style="color:#8b949e"># mapped, not yet touched (subset of Free)</span>
Hugetlb:        34816000 kB     <span style="color:#8b949e"># 33.2 GB locked away from the rest of the OS</span></pre>
</div>

<p>There are two ways this can go wrong. If <code class="language-plaintext highlighter-rouge">Total</code> is <code class="language-plaintext highlighter-rouge">0</code>, you never reserved a pool. If <code class="language-plaintext highlighter-rouge">Total</code> is large but <code class="language-plaintext highlighter-rouge">Free</code> matches <code class="language-plaintext highlighter-rouge">Total</code> and <code class="language-plaintext highlighter-rouge">Rsvd</code> is <code class="language-plaintext highlighter-rouge">0</code>, the pool exists but PostgreSQL did not use it.</p>

<h3 id="sizing-the-reservation">Sizing the reservation</h3>

<p>PostgreSQL documents <a href="https://www.postgresql.org/docs/current/kernel-resources.html#LINUX-HUGE-PAGES">the full procedure</a>, but the short version is this: since PostgreSQL 15, the server tells you exactly how many huge pages it needs, so there is no need to estimate them from <code class="language-plaintext highlighter-rouge">shared_buffers</code>. There are two ways to read this:</p>

<p>On a running server:</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">SHOW</span> <span class="n">shared_memory_size_in_huge_pages</span><span class="p">;</span>   <span class="c1">-- e.g. 16808</span>
</code></pre></div></div>

<p>On a stopped one:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>postgres <span class="nt">-D</span> /var/lib/postgresql/data <span class="nt">-C</span> shared_memory_size_in_huge_pages
</code></pre></div></div>

<p>This parameter is calculated at startup, so <code class="language-plaintext highlighter-rouge">postgres -C</code> can read it <strong>only when the server is shut down</strong>. Against a running instance, it fails because of the <code class="language-plaintext highlighter-rouge">postmaster.pid</code> lock instead of printing a value.</p>

<p>Both commands read the number from the same real server. To see how each setting changes it, you can use a calculator:</p>

<p><strong><a href="/assets/posts/howtoworks_shmem_sizing.html">→ How many huge pages does PostgreSQL need? The sizing calculator</a></strong></p>

<blockquote>
  <p>ℹ️ <strong>About the calculator.</strong> It uses the same formulas as the PostgreSQL source code. Compared with <code class="language-plaintext highlighter-rouge">postgres -C</code> on real PostgreSQL 17 and 18 servers, the difference is up to <strong>0.33%</strong>.</p>
</blockquote>

<h3 id="setting-up-huge-pages-in-linux">Setting up huge pages in Linux</h3>

<p>Take the number above, add <strong>1 - 2%</strong>, then round up to a number you can read at a glance. The pool is managed through <a href="https://docs.kernel.org/admin-guide/mm/hugetlbpage.html"><code class="language-plaintext highlighter-rouge">vm.nr_hugepages</code></a>, and the important setting is the one applied at boot, when memory is least fragmented:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">echo</span> <span class="s1">'vm.nr_hugepages = 17000'</span> <span class="o">&gt;&gt;</span> /etc/sysctl.conf
</code></pre></div></div>
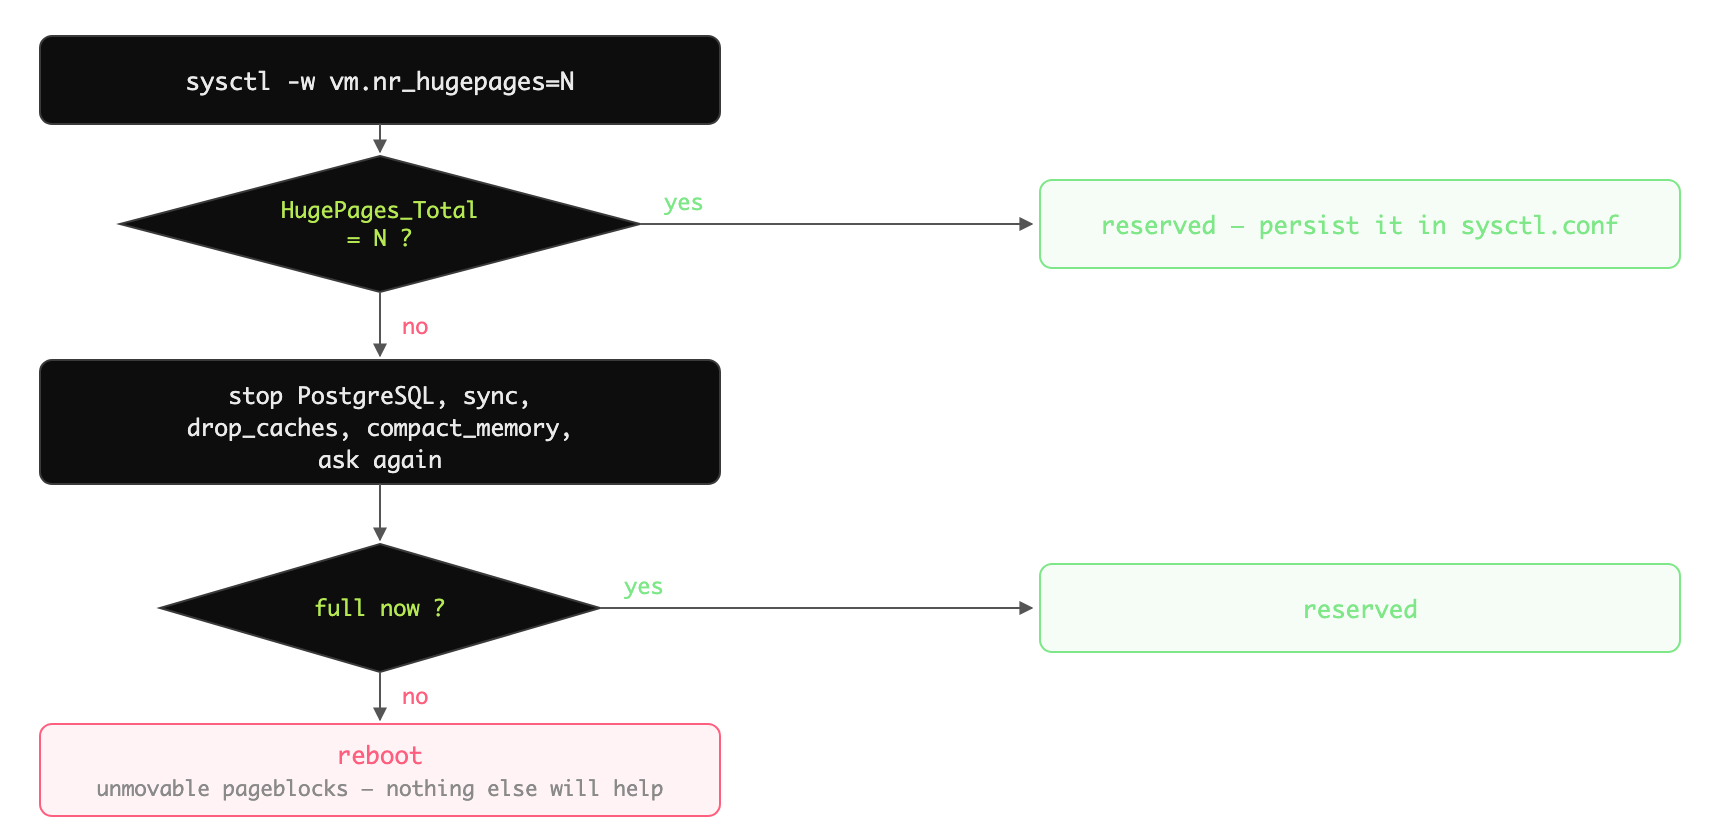
<p><code class="language-plaintext highlighter-rouge">sysctl -w</code> applies the same value immediately and is useful for testing on a live machine, but it is not reliable. On a fragmented system, the kernel can provide <strong>fewer pages than requested without reporting an error</strong>. Always check what you actually received:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sysctl <span class="nt">-w</span> vm.nr_hugepages<span class="o">=</span>17000
<span class="nb">grep </span>HugePages_Total /proc/meminfo    <span class="c"># must equal 17000 — anything lower is a partial allocation</span>
</code></pre></div></div>

<p>If it returns fewer pages than requested, memory is already too fragmented to satisfy the request at runtime. Before you reboot, give the kernel a better chance: stop PostgreSQL, drop the page cache, compact memory, then try again. With the largest consumer gone and the cache released, the request often succeeds:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>systemctl stop postgresql
<span class="nb">sync</span><span class="p">;</span> <span class="nb">echo </span>3 <span class="o">&gt;</span> /proc/sys/vm/drop_caches
<span class="nb">echo </span>1 <span class="o">&gt;</span> /proc/sys/vm/compact_memory
sysctl <span class="nt">-w</span> vm.nr_hugepages<span class="o">=</span>17000
<span class="nb">grep </span>HugePages_Total /proc/meminfo    <span class="c"># check again</span>
</code></pre></div></div>

<p><img src="/assets/images/hugepages-fragmentation.png" alt="When a runtime reservation returns fewer pages than requested" /></p>

<p>Still short — <strong>reboot the machine</strong>, and the value you wrote to <code class="language-plaintext highlighter-rouge">/etc/sysctl.conf</code> above will be applied early in boot, while memory is still largely unfragmented.</p>

<blockquote>
  <p>⚠️ On a multi-socket server, check that <code class="language-plaintext highlighter-rouge">vm.zone_reclaim_mode</code> is <code class="language-plaintext highlighter-rouge">0</code>. When set to <code class="language-plaintext highlighter-rouge">1</code>, the kernel discards local page cache instead of using free memory from a neighbouring node. That costs a database far more than the remote access it avoids. 0 has been the kernel default since Linux 3.16, so this only matters for inherited machines and tuning profiles, not as a setting you would normally change.</p>
</blockquote>

<h3 id="transparent-huge-pages">Transparent Huge Pages</h3>

<p><a href="https://docs.kernel.org/admin-guide/mm/transhuge.html">THP</a> is a different mechanism and does not replace an explicit reservation. It works on a best-effort basis, so the kernel gives you huge pages when it can and may take them back later. The usual advice is to disable it. These are sysfs settings, <strong>not sysctls</strong>, so <code class="language-plaintext highlighter-rouge">/etc/sysctl.conf</code> will not persist them:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cat</span> /sys/kernel/mm/transparent_hugepage/enabled   <span class="c"># current value is the one in brackets</span>
<span class="nb">echo </span>never <span class="o">&gt;</span> /sys/kernel/mm/transparent_hugepage/enabled
</code></pre></div></div>

<p>To make it permanent, add <code class="language-plaintext highlighter-rouge">transparent_hugepage=never</code> to the kernel command line.</p>

<blockquote>
  <p>ℹ️ <strong>About this advice</strong>. “Turn off THP” has been repeated in article after article for over a decade. Now it appears in this one too. I have not tested it on a modern kernel. I think it matters much less today than it did ten years ago. I hope someone tests how THP and PostgreSQL behave on modern kernels.</p>
</blockquote>

<hr />

<h2 id="5-aside-a-pooler-may-be-enough">5. Aside: a pooler may be enough</h2>

<blockquote>
  <p>ℹ️ Notes</p>

  <ul>
    <li>Everything below assumes a pooler in transaction mode.</li>
    <li><strong>An aside, not part of the rollout above.</strong> Page table memory grows for two reasons: the number of backends you run and the size of the pages. Huge pages address the second. A pooler addresses the first, with no reboot, kernel tuning, or reserved memory. Neither replaces the other. A pooler cannot make a page table smaller, and huge pages cannot stop your application from opening 600 connections.</li>
  </ul>
</blockquote>

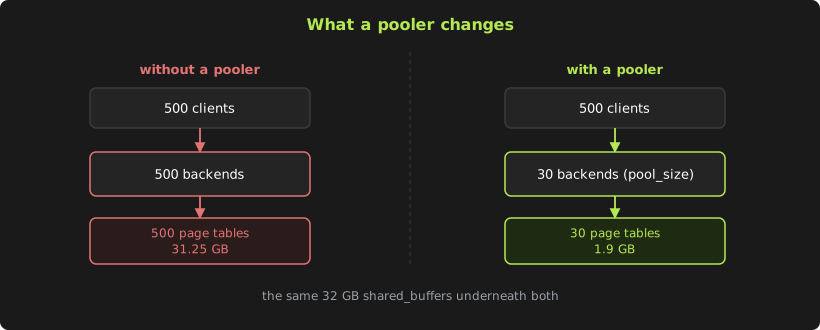
<p><strong><code class="language-plaintext highlighter-rouge">pool_size</code> caps the number of backends</strong>. 500 clients through a pool of 30 create 30 backends, not 500. With 32 GB of <code class="language-plaintext highlighter-rouge">shared_buffers</code>, that is roughly 1.9 GB of page tables instead of 31 GB. Growth depends on the pool size, not on how many connections your application opens.</p>

<p><img src="/assets/posts/hugepages-07-pooler.svg" alt="What a pooler changes: 500 clients become 30 backends, and 31.25 GB of page tables become 1.9 GB" /></p>

<p><strong>Backends stay hot.</strong> Server connections are reused much more often, so each backend’s working set stays warm and its translations remain resident. A server connection lives separately from the client connection that used it, so an application that constantly opens and closes connections does not pay for a new first touch every time. The same helps after a database restart: if the pool uses the most recently used connection first, only a few backends need to warm up.</p>

<p><strong>Recycling removes bloated backends.</strong> Poolers can close server connections after a set lifetime, and the backend with its large page table disappears with the connection. This works regardless of application behaviour, which matters for legacy clients that never close connections.<sup id="fnref:recycle" role="doc-noteref"><a href="#fn:recycle" class="footnote" rel="footnote">4</a></sup></p>

<p><strong>A pooler reduces the scale of the problem, while huge pages reduce the cost per unit</strong>. They solve separate parts of the problem. Together, 30 backends at 128 KB each is not a number worth thinking about.</p>

<p>See also: <a href="/2024/10/01/Effective-PgBouncer-monitoring-using-Odarix.html">Effective PgBouncer monitoring using Odarix</a> and <a href="/2026/01/18/aws-rds-proxy-postgresql.html">AWS RDS Proxy for PostgreSQL</a>.</p>

<hr />

<h2 id="6-conclusion">6. Conclusion</h2>

<p>Huge pages are a narrow optimisation with a clear mechanism. They do not make PostgreSQL faster in general. They remove address-translation overhead, and only for shared memory<sup id="fnref:local" role="doc-noteref"><a href="#fn:local" class="footnote" rel="footnote">5</a></sup> — fewer TLB misses on the same working set. And last but not least, they free the RAM those page tables were using. Whether this is worth doing is not a judgement call. Measure how much your current workload spends on page tables, then decide whether that number is large enough to care about.</p>

<p><strong>Rollout checklist</strong></p>

<ol>
  <li>Measure — <code class="language-plaintext highlighter-rouge">grep '^PageTables' /proc/meminfo</code>. Happy with the number? Stop here.</li>
  <li>Disable transparent huge pages.</li>
  <li>Get the requirement — <code class="language-plaintext highlighter-rouge">SHOW shared_memory_size_in_huge_pages;</code> on the running server.</li>
  <li>Reserve it at boot in <code class="language-plaintext highlighter-rouge">/etc/sysctl.conf</code>, plus a margin.</li>
  <li>Multi-socket box — check <code class="language-plaintext highlighter-rouge">vm.zone_reclaim_mode = 0</code>.</li>
  <li>Choose <code class="language-plaintext highlighter-rouge">huge_pages = on</code>, or <code class="language-plaintext highlighter-rouge">try</code> with an alert.</li>
  <li>Restart if needed. Confirm <code class="language-plaintext highlighter-rouge">HugePages_Free</code> dropped and <code class="language-plaintext highlighter-rouge">huge_pages_status</code> reads <code class="language-plaintext highlighter-rouge">on</code>.</li>
  <li>Re-measure, compare with step 1.</li>
</ol>

<hr />

<h2 id="notes">Notes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:scaling" role="doc-endnote">
      <p>The upper limit assumes every backend has read all of <code class="language-plaintext highlighter-rouge">shared_buffers</code>; 64 MB is the figure for a fully warmed backend. A backend allocates entries only for pages it has actually touched, so its table grows with everything it has read over its lifetime. The longer it lives, the closer it gets to the upper limit. <a href="#fnref:scaling" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:try" role="doc-endnote">
      <p>With <code class="language-plaintext highlighter-rouge">try</code>, PostgreSQL requests <code class="language-plaintext highlighter-rouge">MAP_HUGETLB</code> and, if that fails, silently retries the mapping without it. The server starts, looks healthy, and runs on 4 KB pages. This usually happens when <code class="language-plaintext highlighter-rouge">vm.nr_hugepages</code> was never set, when it is too small after <code class="language-plaintext highlighter-rouge">shared_buffers</code> grows, or when it was set with <code class="language-plaintext highlighter-rouge">sysctl -w</code> but never saved to <code class="language-plaintext highlighter-rouge">/etc/sysctl.conf</code>, so it disappeared at the last reboot. <a href="#fnref:try" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:status" role="doc-endnote">
      <p><code class="language-plaintext highlighter-rouge">huge_pages_status</code> was added in PostgreSQL 17 because <code class="language-plaintext highlighter-rouge">try</code> gave no way to confirm the result. A running instance reports either <code class="language-plaintext highlighter-rouge">on</code> or <code class="language-plaintext highlighter-rouge">off</code>. The third value, <code class="language-plaintext highlighter-rouge">unknown</code>, means the status could not be determined. You see it when reading the parameter with <code class="language-plaintext highlighter-rouge">postgres -C</code> against a stopped server, because nothing has been allocated yet. <a href="#fnref:status" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:recycle" role="doc-endnote">
      <p>Recycling removes warm page tables along with bloated ones. If the lifetime is too short, you get a steady stream of re-faults, fork costs, and a cold catalog cache for every new backend. This is a trade-off between steady-state table size and fault frequency, not a free win. Most poolers also offer an idle-based equivalent. It does the same thing based on idleness rather than age and is usually the cheaper option. In PgBouncer, these are <a href="https://www.pgbouncer.org/config.html"><code class="language-plaintext highlighter-rouge">server_lifetime</code> and <code class="language-plaintext highlighter-rouge">server_idle_timeout</code></a>; other poolers use different names for the same two ideas. <a href="#fnref:recycle" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:local" role="doc-endnote">
      <p><code class="language-plaintext highlighter-rouge">work_mem</code>, <code class="language-plaintext highlighter-rouge">maintenance_work_mem</code>, and catalog and plan caches still use 4 KB pages. Huge pages apply only to the shared memory segment. <a href="#fnref:local" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Marat Bogatyrev</name></author><category term="planet" /><summary type="html"><![CDATA[Your server keeps a page table — a structure in RAM that only describes where other memory is located. Each process has its own, with one 8-byte entry for every 4 KB page it has actually used. In PostgreSQL, every connection has its own backend, and each backend is a separate OS process — so each one holds a private description of the same shared_buffers. The more memory you give the database and the more connections you run, the more RAM is used just to describe memory you already own. On a typical production server with 32 GB of shared_buffers and 600 backends, this can easily reach 10 - 20 GB: RAM wasted on describing RAM.]]></summary></entry></feed>